Local bench
The card xAI published for Grok 4.7, set next to an empty column for a model that runs on this server. A filed run fills that column. The gap is the case for a distilled build a person can own.
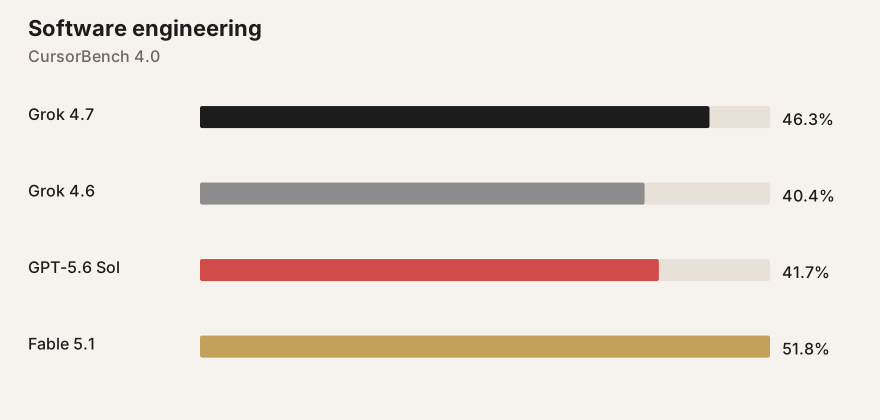
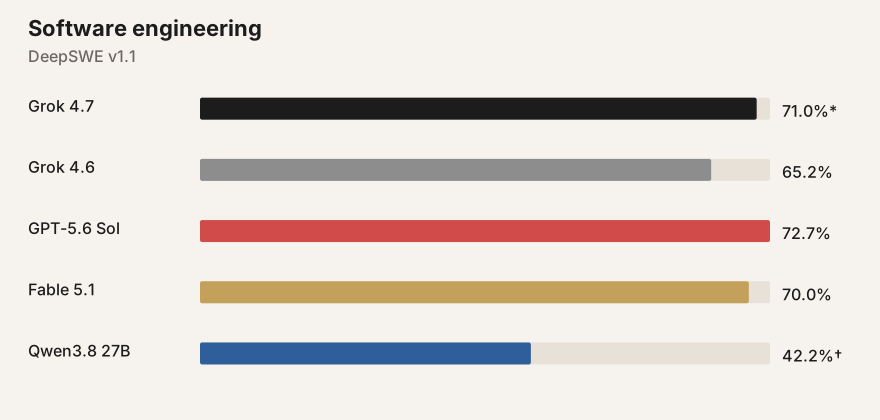
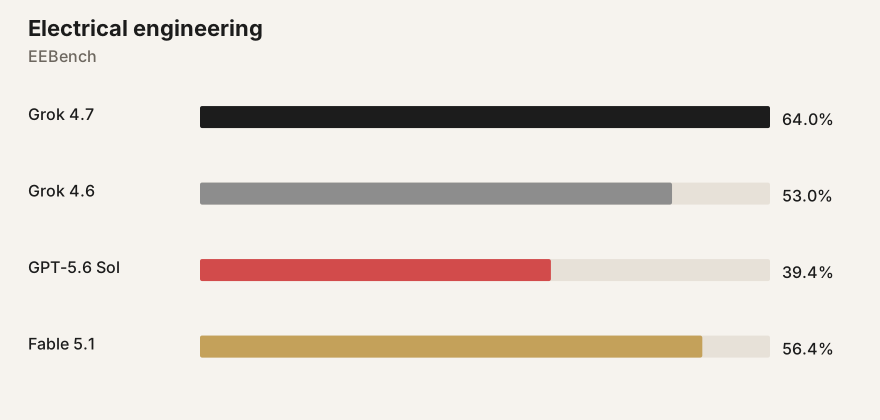
The table and the bar charts are the Grok 4.7 launch card from 21 Sep 2026. Bold is the best number on that row. The asterisk on DeepSWE is high effort. The Qwen3.8 27B column is the full-weight model card, not the Q4_K_M file on this server. The dagger on its DeepSWE score is Claude Code at temperature 1.0 with a 256K context. A run of a quant that fits these cards shows up as its own column.
Grok 4.7 launch card
| Grok 4.7 xHigh | Grok 4.6 High | GPT-5.6 Sol Max | Fable 5.1 Max | Qwen3.8 27B full weights | This server your run | |
|---|---|---|---|---|---|---|
| Software engineering CursorBench 4.0 | 46.3% | 40.4% | 41.7% | 51.8% | — | — |
| Software engineering DeepSWE v1.1 | 71.0%* | 65.2% | 72.7% | 70.0% | 42.2%† | — |
| Electrical engineering EEBench | 64.0% | 53.0% | 39.4% | 56.4% | — | — |
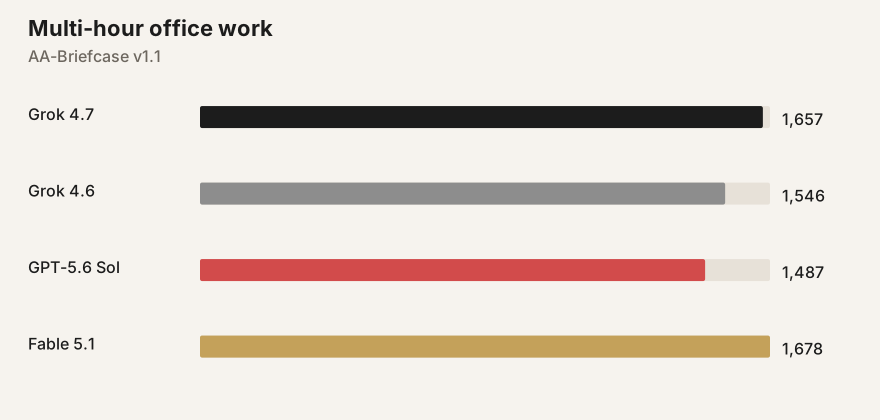
| Multi-hour office work AA-Briefcase v1.1 | 1,657 | 1,546 | 1,487 | 1,678 | — | — |
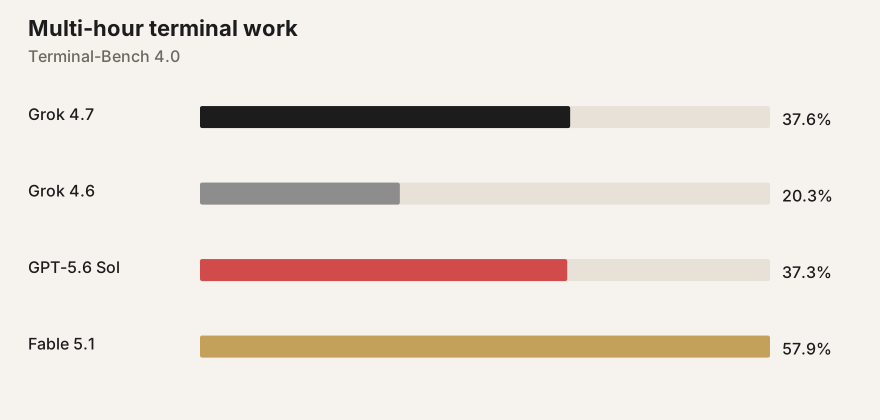
| Multi-hour terminal work Terminal-Bench 4.0 | 37.6% | 20.3% | 37.3% | 57.9% | — | — |
| Legal work Harvey Legal Agent | 19.6% | 15.8% | 2.5% | 6.7% | — | — |
| Clinical reasoning HealthBench Pro | 56.7% | 48.5% | 60.5% | 62.1% | — | — |
| Input token price $ per million | $2 | $2 | $4 | $10 | — | — |
| Output token price $ per million | $6 | $6 | $20 | $50 | — | — |
* High effort. † Qwen3.8 27B full weights, Claude Code, temperature 1.0, 256K context. That column is not the Q4_K_M on this server. Three RTX 5060 Ti cards, 16 GB each. A 16 GB run used one card. A 48 GB run used the whole server.
The same card, one chart at a time
Each row of the card as a bar chart, the shape of the other graphs on that launch. Download the SVG for a post.
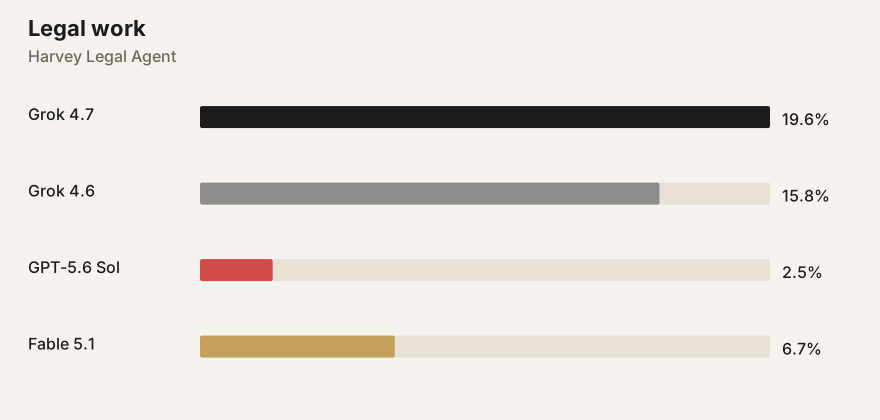
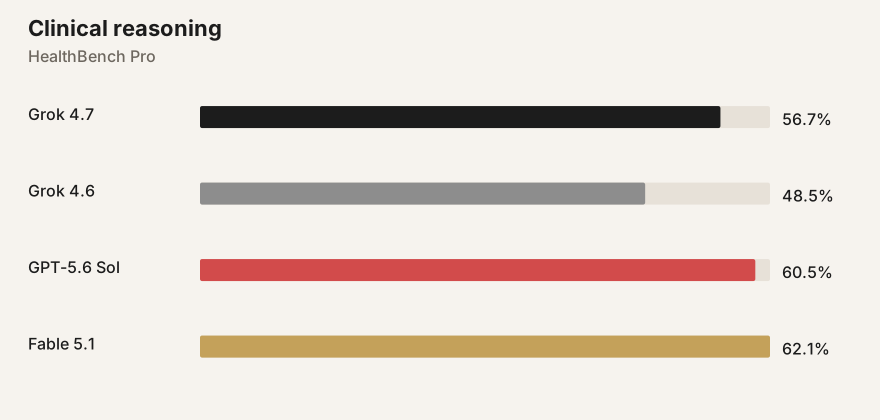
Older cards that still print a score
| Test | Model | Score | Conditions |
|---|---|---|---|
| AIME 2025 | GPT-5.2 Thinking | 100 | Lab published, no tools |
| AIME 2025 | Claude Opus 4.6 | 99.8 | Lab published, no tools, 5-trial average |
| GPQA Diamond | GPT-5.6 Sol | 94.6 | Lab published |
| GPQA Diamond | Claude Opus 4.7 | 94.2 | Lab published, 10-trial average |
| LiveCodeBench | Qwen3.8 27B | 90.3 | LiveCodeBench v6, Qwen model card |
| GPQA Diamond | Qwen3.8 27B | 89.2 | Qwen model card |
| SWE-bench Verified | Claude Opus 4.7 | 87.6 | Lab published |
| SWE-bench Verified | GPT-5.2 Thinking | 80 | Lab published |
| HLE, no tools | Claude Opus 4.7 | 46.9 | Lab published, no tools, max effort |
| HLE, no tools | GPT-5.2 Thinking | 34.5 | Lab published, no tools |